
🎙️ whisper-captions
Whisper, but caption-ready. Turn whisper.cpp output into clean segments with whole-word timestamps, and export SRT or WebVTT.



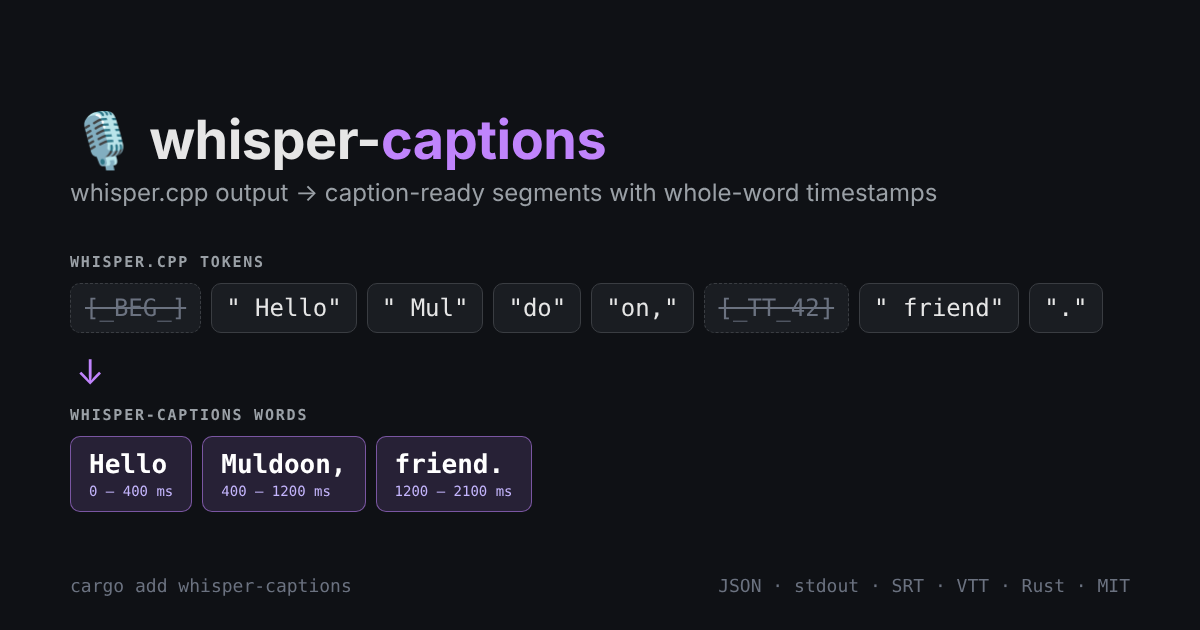
whisper.cpp is great at transcribing speech, but its word-level output is made of BPE tokens, not words. Join them naively and your captions read M uld oon, was p or friend ., and control tokens like [_BEG_] and [_TT_150] leak into the text.
whisper-captions is a small, open-source Rust crate that fixes exactly that. It reads whisper.cpp's JSON or stdout, reassembles tokens into whole words with start and end times, drops the special tokens and gives you segments that are ready for a subtitle track.
📦 Get it
cargo add whisper-captionsCrates.io: crates.io/crates/whisper-captions
Documentation: docs.rs/whisper-captions
Changelog: CHANGELOG.md
🚀 Features
- 📥 Reads every whisper.cpp output you are likely to have:
-oj,-ojf(full JSON with tokens) and plain stdout - 🧩 Reassembles BPE tokens into whole words with start and end times
- 🧹 Drops special tokens:
[_BEG_],[_TT_150],<|endoftext|> - ⏱️ Normalizes whitespace and timestamps (strings, seconds or milliseconds)
- 🎬 Exports SRT and WebVTT
- 🪶 No whisper dependency: works on output files from any whisper.cpp version
- 🤝 The token merger also accepts tokens from
whisper-rs - 🧾 Serde-ready output in camelCase, easy to hand to a frontend
🦀 Example: whisper.cpp JSON to SRT
// whisper-cli -m ggml-base.en.bin -f audio.wav -ojf -of out
let json = std::fs::read_to_string("out.json")?;
let segments = whisper_captions::parse_whisper_json_str(&json)?;

for segment in &segments {
    println!("{}–{} ms: {}", segment.start_ms, segment.end_ms, segment.text);
    for word in &segment.words {
        println!("    {:>6} ms  {}", word.start_ms, word.text);
    }
}

std::fs::write("out.srt", whisper_captions::to_srt(&segments))?;
💻 Example: from the command line
The repository ships a small whisper2srt example:
cargo run --example whisper2srt -- out.json > out.srt
cargo run --example whisper2srt -- stdout.txt --vtt > out.vtt
🎯 Built for
- Caption and subtitle editors that need word timings for karaoke-style or per-word captions
- Video pipelines that run whisper.cpp and want SRT or VTT without extra tooling
- Desktop apps on Tauri or Electron, where the parsing should be fast and dependency-free
- whisper-rs projects that want clean words instead of raw tokens
🎬 Born in Flixlar
whisper-captions was extracted from Flixlar, my local-first caption editor, where it turns whisper.cpp auto-captions into editable subtitle tracks as a native Rust module. Flixlar needed it, so it is shaped by a real caption workflow, not a demo.
🤝 Need speech-to-text in your product?
I build with Whisper, FFmpeg and Rust: transcription and captioning pipelines, subtitle tooling, and desktop or backend integrations around them. I take on freelance work.
Selected Projects
A glimpse into the tools, love, and tech behind what I build.
Flixlar
Desktop caption editor for fast video workflows.
GIFmeta
Command-line and open-source toolkit for editing GIF metadata.
evmify
Open-source Rust crate: one API for EVM and non-EVM blockchains, always in EVM format.
whisper-captions
Open-source Rust crate: whisper.cpp output to caption-ready segments with word timings, SRT and VTT.
Aether Renderer
Modular CLI and GUI renderer for generating video from image sequences.
mySiteChart
Lightweight service for visualizing analytics and user insight without complexity.
Sacred AI
A digital sanctuary for emotional healing and conflict resolution.
Digital Art Archive
Personal art and cultural preservation projects.
ownPost
Browser extension that lets you share your own articles to LinkedIn in one click.